Every company preparing for AI hits the same wall. The models are ready. The tools are available. In most organizations, the data isn’t.
I ran into this firsthand earlier in my career, and it later inspired me to build the North Star App. Without a proper data infrastructure, too many ideas, opportunities, and challenges go unnoticed. Not because the organization lacks the information, but because it has no way to combine sources and turn what it knows into a structural overview.
Two recent studies make the scale of the problem concrete. Research from the IBM Institute for Business Value in March 2026 identifies the lack of a solid data infrastructure as one of the top barriers preventing companies from adopting AI at scale. The Gartner® study published in April 2026, based on interviews with 782 infrastructure and operations leaders, found that only 28% of AI projects met or exceeded expected ROI. The remaining 72% fell behind. Not because the AI failed technically, but because the foundation beneath it wasn’t ready.
In this article, I’ll explore what data infrastructure for AI actually consists of, what causes it to fail, and where to start if you are building one now.
What data infrastructure for AI actually means
Data infrastructure is the layer that sits beneath analytics, BI tools, and any AI system your organization uses. Without it, teams cannot trust or use their data efficiently, which means they also cannot trust anything the AI derives from it.
The IBM study defines the core components as:
- Data sources and data ingestion
- Storage and compute
- Data transformation
- Governance, security, and observability
- Data serving and data analytics
- Machine learning and machine operations (MLOps)
- Data collaboration
Most companies have parts of this in place. Few have it working as one system. The typical picture is a warehouse receiving data from three or four critical sources, several important sources still exported manually, transformations happening in three different places, and no clear owner for any of it. That is the configuration AI initiatives are being launched on top of, and it is why so many stall.
Why AI initiatives fail
The Gartner research identifies the main causes of AI project failure as:
- Skill gaps
- Overly ambitious goal-setting
- Unaligned expectations
- Poor AI readiness
- Limited data availability
Two of these will improve on their own as teams gain experience: skill gaps and unaligned expectations. The other three are infrastructure problems. Poor AI readiness usually means the data is not organized in a way the AI can use. Limited data availability usually means the right sources are not connected. Overly ambitious goal-setting usually means someone committed to an outcome the underlying data cannot support.
These are solvable now. And they are worth solving now, because the cost of trying to build AI capability on top of a fragmented data layer compounds every quarter it is delayed.
How to build data infrastructure for AI: a practical checklist
There is no single correct architecture. But the following steps consistently separate the organizations that get value from AI from the ones that do not:
- Start with business questions. Define the decisions your data should improve before choosing tools.
- Connect every critical source. Bring marketing, sales, finance, and operational data into one reliable flow.
- Automate collection. Replace manual exports with scheduled refreshes to keep reports up-to-date and reduce errors.
- Standardize and validate. Align formats, naming conventions, and metrics so teams work from consistent numbers.
- Centralize access. Send clean data to the warehouse, spreadsheet, or BI platform that best fits your scale.
- Design for usability. Build focused dashboards that highlight decisions, not every metric available.
- Protect the foundation. Set clear ownership, access controls, monitoring, and recovery procedures.
- Choose infrastructure that can grow. Pick a data integration layer that can scale as your sources and use cases expand, without needing a large engineering team behind it.
- Improve continuously. Review broken workflows, unused reports, and changing business needs every quarter to keep the data relevant.
The bullets are simple. The work is not. Most organizations will find at least three of these are handled poorly today, and picking the right one to fix first is often the hardest decision in the process.
Don’t overlook what your people already know
The data infrastructure conversation almost always focuses on connecting SaaS tools, cleaning databases, and defining metrics. That is necessary work. It is not sufficient.
Every employee knows what it takes to succeed in their role: the challenges they run into, the opportunities they see, and the areas where things could work better. When those insights go uncommunicated or undocumented, they go unused. Not because the ideas were bad, but because the data was never collected or requested in the first place. This is one of the most consistent gaps I see in how organizations think about their data.
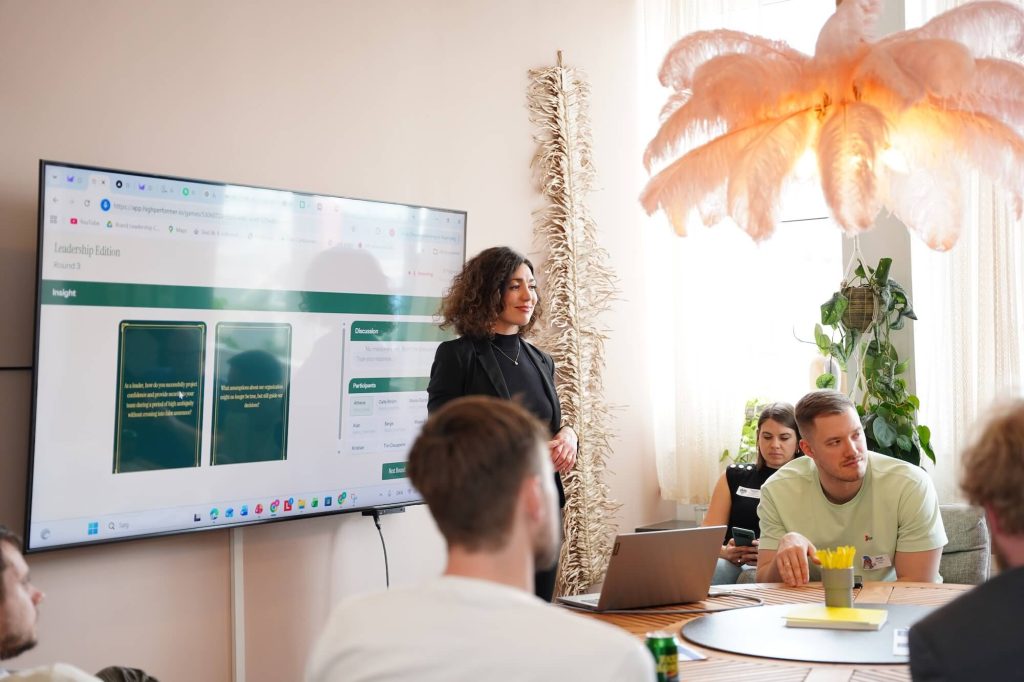
At North Star, this is the specific problem I have been working on: giving organizations a repeatable way to collect insights, challenges, and ideas from the people closest to the work.
While testing prototypes of the North Star App at MeasureCamp analytics conferences in Denmark, Sweden, and Finland, I have seen the same observations surface among professionals across different organizations and cultures. The fact that these issues recur so consistently, across unrelated companies, team structures, and countries, suggests they are not isolated problems. They point to a category of business context that most data infrastructure setups do not capture, and that no amount of connecting SaaS tools will surface on its own.

For AI initiatives, this matters more than it did for traditional analytics. AI works with the context it is given. If the context is incomplete, the interpretation will be too, and the fluency of the output will make the gap harder to notice, not easier.
The value of a modern data infrastructure
Based on my experience with product development, most companies look for solutions that take the least time and effort while producing the highest-quality output. When you are selecting which systems to put in place, this should always be a consideration. Your time and your employees’ time are among your most valuable resources.
The payoff of getting the infrastructure right shows up in ways that are difficult to see from inside a fragmented setup. Data stays up to date and available to the people who need it. Silos become harder to maintain. Handovers between teams stop losing important context. Departments still measure success differently, but the underlying numbers stop contradicting each other. As a result, conversations about priorities become conversations about tradeoffs rather than whose data to trust.
Building the pipes from scratch takes more engineering capacity than most organizations have on hand, which is why integration platforms are worth looking at rather than trying to custom-build. Coupler.io is one I would put on that shortlist. It handles the connect-and-prepare work across over 400 business apps and gets the data into whatever your team already uses, whether that is a spreadsheet, a warehouse, a BI tool, or an AI assistant. And you don’t need a dedicated engineering team to keep it running.


Unify your data stack with Coupler.io
Book a demoWhen employees have access to shared data instead of separate metrics, they also stop spending hours on repetitive administrative work that could be automated. That opens up time for the projects that actually move business outcomes.
Where to start
You do not need to solve this all at once. Pick your most fragmented data process, the one that eats the most hours or produces the least trust, and fix that flow first. Automate the collection, standardize the metrics, and route it into one place your team already checks.
Get that one right, and the case for doing the rest builds itself